Confidence interval
Confidence Interval: Definition, Formula and Worked Examples
A poll says 49 percent of voters back a candidate. Nobody believes that the real figure is exactly 49. The poll asked only a few thousand people, so the real figure is somewhere near 49. The question is how near. A confidence interval answers that, with a range such as 47 to 51 percent.
This idea is everywhere in data science. Model accuracy, A and B test results, survey findings and average delivery times are all estimates from samples. A single number without a range can mislead. A confidence interval shows how much to trust the estimate.
This tutorial explains what a confidence interval is, what the confidence level really means, the formula, a fully worked example with the answer, how the level and sample size change the width, how to handle small samples with the t distribution, and how to calculate it in Python.
Confidence Interval Definition
A confidence interval is a range of values, calculated from sample data, that is likely to contain the true population value. It is made of a point estimate, such as the sample mean, plus and minus a margin of error.
It measures uncertainty. A narrow interval means that the estimate is precise. A wide one means that it is rough.
What the Confidence Level Means?
The confidence level describes the method, not one single interval. Suppose you repeat the sampling many times and build an interval each time. At a 95 percent level, about 95 percent of those intervals will contain the true value, and about 5 percent will miss it. At a 90 percent level, about 90 percent will contain it.
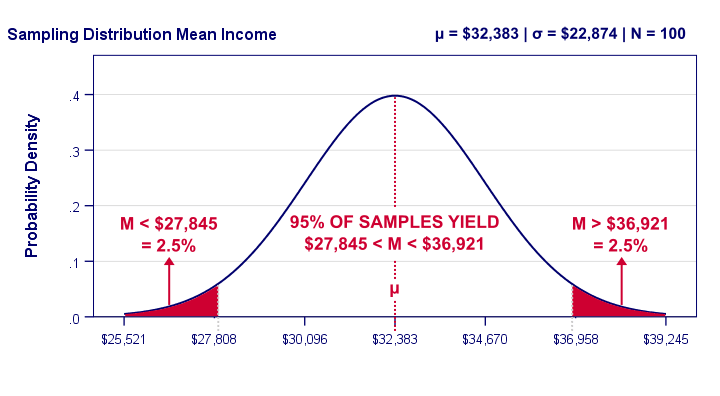
The live page says the true value falls between the interval 92 percent of the time. That is a common slip. The true value is fixed, and it does not move. It is the interval that changes from sample to sample.
A quick check, which I ran: I drew 10,000 samples of 100 values from a population with a true mean of 16 and a standard deviation of 3. I built a 95 percent interval from each. The share of intervals that contained 16 was 0.9488, very close to 95 percent.
Why do We Use a Confidence Interval?
- To show uncertainty. A result such as 49 percent plus or minus 2 is more honest than 49 percent alone.
- To compare results. If two intervals do not overlap, the difference is probably real.
- To plan. A narrow interval helps you decide whether you have enough data.
- To link with testing. A two tailed test at 0.05 rejects a value exactly when it is outside the 95 percent interval.
How to Calculate a Confidence Interval?
For a mean, when the population standard deviation is known:
The part after the plus or minus sign is the margin of error. Z comes from the confidence level:
| Confidence level | Z value | Tail area each side |
|---|---|---|
| 90 percent | 1.645 | 0.05 |
| 95 percent | 1.960 | 0.025 |
| 99 percent | 2.576 | 0.005 |
- Find the sample mean and the sample size n.
- Choose the confidence level, and find z.
- Calculate the standard error: the standard deviation divided by the square root of n.
- Multiply by z to get the margin of error.
- Add and subtract the margin from the mean.
Confidence Interval Example
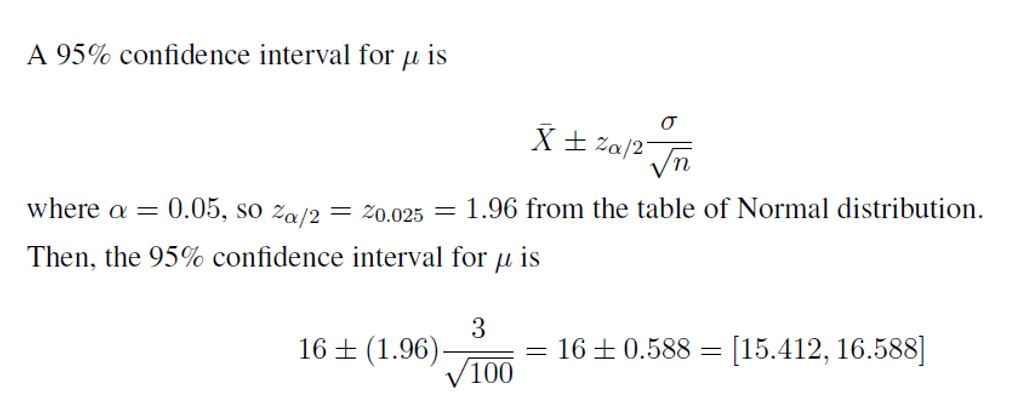
The live page: n = 100, sample mean = 16, standard deviation = 3. Find the 95 percent interval for the population mean. The live page writes the standard deviation as mu. The right symbol is sigma. It also leaves out the answer.
- Standard error = 3 divided by the square root of 100 = 0.3.
- Z for 95 percent = 1.96.
- Margin of error = 1.96 times 0.3 = 0.588.
- Interval = 16 plus or minus 0.588 = 15.41 to 16.59.
Meaning: we are 95 percent confident in the method that produced this range. A fair plain statement is that the population mean is likely between 15.41 and 16.59.
How the Confidence Level Changes the Width?
| Level | Z | Margin of error | Interval |
|---|---|---|---|
| 90 percent | 1.645 | 0.493 | 15.51 to 16.49 |
| 95 percent | 1.960 | 0.588 | 15.41 to 16.59 |
| 99 percent | 2.576 | 0.773 | 15.23 to 16.77 |
A higher level gives a wider interval. You trade precision for confidence.
How the Sample Size Changes the Width?
| Sample size | Margin at 95 percent | Interval |
|---|---|---|
| 25 | 1.176 | 14.82 to 17.18 |
| 100 | 0.588 | 15.41 to 16.59 |
| 400 | 0.294 | 15.71 to 16.29 |
Four times the data halves the margin. The square root of n is why. Doubling your data does not halve the error.
Confidence Interval for a Proportion: Poll Example
The live page describes an election poll, but the example has no source and unclear numbers, so I use a made up one. A poll of 2,400 voters finds that 49 percent support a candidate.
- Standard error = square root of (0.49 times 0.51 divided by 2400) = 0.0102.
- Margin of error at 95 percent = 1.96 times 0.0102 = 0.02, or 2 points.
- Interval = 47 percent to 51 percent.
The interval is wide enough to include a tie or a lead for the other side. That is why a poll with a 49 to 48 result is a statistical tie. Also, the margin of error covers random sampling error only. It does not cover bad question wording or a sample that is not representative.
Small Samples: The T Interval
When the population standard deviation is unknown and the sample is small, replace z with a t value that depends on the degrees of freedom, n minus 1. The t value is larger than z, so the interval is wider. With 10 measurements, the t value at 95 percent is 2.262. The standard deviation is calculated from the sample itself.
Calculate a Confidence Interval in Python
I ran the code below, and the output is real.
Common Mistakes to Avoid
| Mistake | Fix |
|---|---|
| Saying there is a 95 percent chance the true value is in this interval | Say that the method captures the true value 95 percent of the time |
| Writing mu for the standard deviation | Mu is the mean, and sigma is the standard deviation |
| Using z for a small sample with unknown sigma | Use the t value |
| Thinking a wider interval is worse | It is the price of higher confidence |
| Ignoring bias in the sample | A confidence interval does not fix a bad sample |
| Comparing results by overlap alone | Overlap is a rough guide, so test the difference |
| Reporting the estimate without the interval | Always show both |
Practice Questions
- n = 64, mean = 50, sigma = 8. Find the 95 percent interval.
- What happens to the margin of error if you raise the level from 95 to 99 percent?
- What happens to the margin if the sample size goes from 100 to 400?
- A 95 percent interval for a mean is 12.1 to 13.9. Is 14 a plausible value?
Answers: 1) Standard error 1, margin 1.96, so 48.04 to 51.96. 2) It grows, from 1.96 to 2.576 times the standard error. 3) It halves. 4) No, because 14 is outside the interval. These are my own answers, so please recheck them before publishing.
A confidence interval turns a single guess into an honest range. Report it with every estimate, choose the level before you look at the data, and remember that the level describes the method, not one interval. A wide range is not a failure. It is the data telling you how sure you can be.
