Correlation vs Causation
Correlation and Causation: Definition, Difference and Examples
A study finds that cities with more ice cream sales also have more sunburn cases. Should the council ban ice cream to cut sunburn? Of course not. Hot weather drives both. This small story holds the most important lesson in data analysis: two things moving together does not mean that one causes the other.
Every data scientist meets this problem on day one. You will find correlations in almost any dataset, and each one tempts you to tell a story. A marketing manager sees that customers who open more emails buy more, and wants to send more emails. Sometimes that works. Sometimes the buyers were simply the more interested people to begin with.
This tutorial explains what correlation and causation are, how they differ, how the correlation coefficient is calculated with a worked example, where it misleads, and how analysts establish that something really causes something else. You will also see three small simulations, run in Python, that make the ideas concrete.
Correlation and Causation Definition
Correlation is a statistical measure of how two variables move together. When one rises, the other tends to rise as well (positive correlation) or tends to fall (negative correlation). It tells you the strength and direction of a relationship.
Causation means that a change in one variable produces a change in the other. One event is the result of the other. Causation is a stronger claim, because it says why the relationship exists.
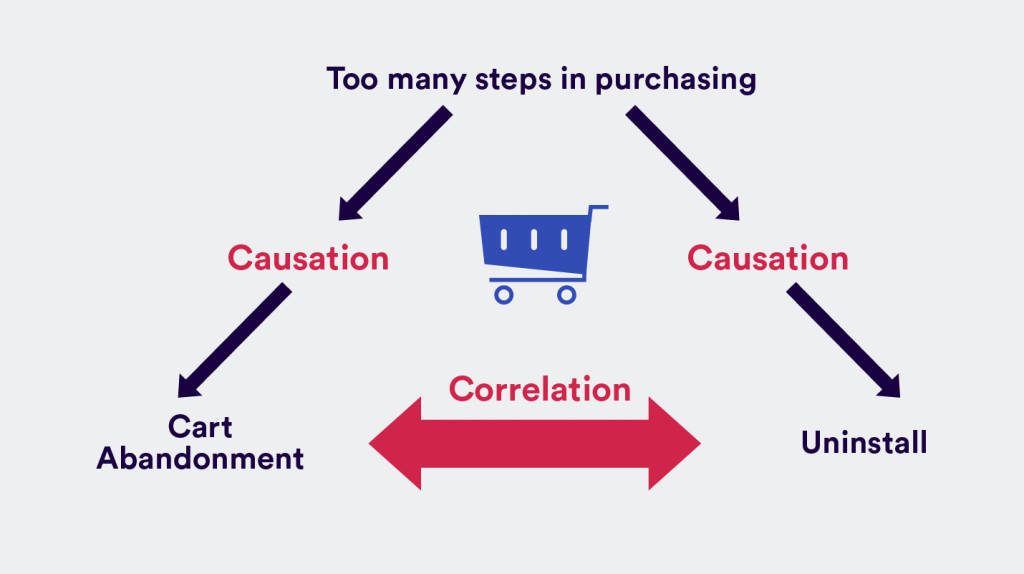
Difference Between Correlation and Causation
| Point | Correlation | Causation |
|---|---|---|
| What it says | Two variables move together | One variable produces a change in the other |
| Direction | Not needed. A and B just go together | One way: cause, then effect |
| Can be shown with | Data and a correlation coefficient | A controlled experiment, or strong causal evidence |
| Example | Ice cream sales and sunscreen sales rise together | A drug lowers blood pressure, shown in a trial |
| Risk | Reading too much into it | Claiming it without proof |
Why are Correlation and Causation Important?
- Better decisions. If you act on a correlation that is not causal, the action will not change the result. Sending more emails to everyone does not make people more interested.
- Finding leads. Correlations are a cheap way to spot what to investigate.
- Predicting. For prediction alone, a correlation is enough. If sunscreen sales rise, expect ice cream sales to rise. You do not need to know why.
- Honest reporting. Saying X causes Y without proof can mislead readers and customers.
The question to ask is whether you want to predict or to intervene. For predicting, correlation often works. For deciding what to change, you need causation.
How is Correlation Measured?
The most common measure is the Pearson correlation coefficient, written r. It runs from minus 1 to plus 1.
| Value of r | Meaning |
|---|---|
| Close to plus 1 | A strong positive relationship. The variables rise together |
| Close to minus 1 | A strong negative relationship. When one rises, the other falls |
| Close to 0 | No straight line relationship |
A rough rule of thumb is that 0.7 or more in size is strong, about 0.4 to 0.7 is moderate and below 0.3 is weak. These cut offs are only a convention, and different fields use different ones. The size that matters depends on your use.
The Formula
Here x bar and y bar are the means of the two variables. The top part checks whether the two variables are above or below their means at the same time. The bottom part scales the answer so it always lands between minus 1 and plus 1.
A Worked Example: Hours Studied and Marks
Here is a small, made up dataset of eight students. It is for teaching, not real data.
| Hours studied (x) | Marks (y) |
|---|---|
| 1 | 35 |
| 2 | 42 |
| 3 | 50 |
| 4 | 55 |
| 5 | 62 |
| 6 | 66 |
| 7 | 75 |
| 8 | 80 |
- The mean of x is 4.5 and the mean of y is 58.125.
- The sum of (x minus x bar) times (y minus y bar) is 267.5.
- The sum of (x minus x bar) squared is 42, and the sum of (y minus y bar) squared is 1710.875.
- r = 267.5 divided by the square root of (42 times 1710.875) = 267.5 divided by 268.06 = 0.998.
A value of 0.998 is a very strong positive relationship. Squaring it gives 0.996. This r squared value says that about 99.6 percent of the variation in marks goes along with variation in hours studied, in this made up data. Real data is much messier.
Even here, correlation alone does not prove that study time raises marks. Students who study more may also be more motivated, or more able. Only a design that controls for these can tell.
Limitations of the Correlation Coefficient
The coefficient is useful, but it has limits that every analyst must know.
1. It Only Measures Straight Line Relationships
Take x from minus 5 to 5, and let y equal x squared. The relationship is perfect, since x decides y exactly. But r is 0.0, because the left half goes down and the right half goes up, and they cancel. The Spearman rank correlation is also 0.0 here. Always plot your data. A number alone can hide a curve.
2. Outliers Can Change It a Lot
Ten pairs of values that rise together have r = 0.939. Add one extreme point, 30 on one axis and minus 20 on the other, and r becomes minus 0.754. One point flipped the sign. Check for outliers before you trust r.
3. It Does Not Show Cause
This is the main point of this page, and the next sections show why.
4. A Third Variable Can Create It
A variable that affects both of your variables is called a confounder, or a lurking variable. It can make two unrelated things look linked. This is shown below.
Pearson and Spearman
Pearson measures straight line relationships and uses the actual values. Spearman ranks the values first, so it captures any relationship that keeps going in one direction, and is less affected by outliers. It still gives 0 for a curve like x squared that goes down and then up.
How Can Causation Be Established?
The strongest method is a randomised controlled experiment. You split people at random into two groups, give one group the treatment, and give the other a placebo or the current option. Because the groups are chosen by chance, they are alike in every other way on average, so a difference in results can be credited to the treatment.
When experiments are not possible or not ethical, analysts use observational studies. For instance, you cannot ask people to start smoking. In these, you try to account for other factors, and you look for supporting signs: a strong and steady relationship, the cause coming before the effect, a plausible mechanism, and similar findings in other studies. These raise confidence. They are weaker than an experiment.
In business, the equivalent of the controlled experiment is the A and B test, where users are randomly shown version A or version B of a page or email.
Correlation and Causation Examples
Example 1: Hours Worked and Salary
People who work more hours often earn more. That is a correlation, and a causal story is plausible, since more hours can mean more pay. But the direction can run the other way. A high wage per hour can encourage people to work more hours. And a third factor, such as a demanding job, can drive both. Without an experiment, you cannot tell which story is true.
Example 2: Ice Cream and Sunscreen Sales
Both sell more on hot days. The sales of one do not cause the sales of the other. Hot weather is the confounder. I simulated one year of daily data to show it. The numbers are made up, but the pattern is real.
| Pair | r |
|---|---|
| Ice cream and sunscreen sales | 0.729 |
| Ice cream sales and temperature | 0.918 |
| Sunscreen sales and temperature | 0.788 |
| Ice cream and sunscreen, after removing the effect of temperature from both | 0.021 |
The raw correlation of 0.73 looks strong. Once temperature is taken out, it falls to almost zero. This is a standard way to test whether a confounder explains a relationship.
Example 3: A Placebo Trial
Researchers want to know if a new drug lowers symptoms. They give the drug to one group and a placebo to the other, chosen at random. In my simulation of 100 patients in each group, the average improvement was 4.79 points on the drug and 2.85 on the placebo. A t test gave a very small p value, about 3 times 10 to the power minus 12. The gap is far larger than chance would produce, and because the groups were chosen at random, the researchers can say the drug caused the extra improvement. Again, the data are made up.
Example 4: Email Opens and Purchases
Customers who open more emails buy more. Do emails cause purchases? Maybe. But keen customers both open emails and buy. To find out, send a campaign to a random half of the customers and compare purchases. If the sent group buys more, the emails did something.
Calculate Correlation in Python
I ran the code below, and the output is real.
Common Mistakes to Avoid
| Mistake | Fix |
|---|---|
| Saying a correlation proves cause | Look for a confounder, or run an experiment |
| Trusting r without a plot | Always draw a scatter plot |
| Ignoring outliers | Check the effect of removing them |
| Calling r a strong result because it is 0.5 in a field that needs more | Judge by the use and by your field |
| Mixing up the direction of cause | Ask whether B could cause A |
| Concluding that no correlation means no relationship | A curve can have r of 0 |
| Testing many pairs and reporting the best | With enough pairs, some will correlate by chance |
Practice Questions
- A study finds that the number of firefighters at a fire correlates with the damage caused. Does that mean firefighters cause damage? Explain.
- A dataset has r = minus 0.8 between the price of a product and its sales. Describe the relationship.
- Why can r be 0 when y equals x squared?
- How would you test whether a new website layout causes more sign ups?
Answers: 1) No. The size of the fire is the confounder. Bigger fires bring more firefighters and cause more damage. 2) A strong negative relationship. Higher prices go with lower sales. It does not prove price caused the drop. 3) The left and right halves of the curve go in opposite directions and cancel, so there is no straight line trend. 4) Run an A and B test, showing the old and new layouts to randomly chosen visitors, and compare sign up rates. These are my own answers, so please recheck them before publishing.
Correlation is a clue, and causation is a conclusion. Plot your data, look for the third variable, think about which way the cause could run, and use an experiment when the decision matters. That discipline separates data analysis that helps from data analysis that misleads.
