Empirical rule
Empirical Rule (68 95 99.7 Rule): Definition, Formula and Examples
A class of Class 6 students has an average height of 1.5 metres. A boy is 1.66 metres tall. Is he unusually tall? You do not need a table or a calculator to get a first answer. The empirical rule says how much of a bell shaped data set lies within one, two and three standard deviations of the mean, and from that you can see that 1.66 is rare.
The rule is quick, easy to remember and good for sanity checks. Quality teams use it to set limits, analysts use it to spot outliers, and students meet it first when they learn the normal distribution. It is also called the 68 95 99.7 rule or the three sigma rule.
This tutorial explains the rule, the correct formula, a fully worked example with the numbers, what happens when the data are not normal, how it differs from Chebyshev’s inequality, and how to check it in Python.
What is the Empirical Rule in Statistics?
The empirical rule is a rule of thumb for data that follow a normal, bell shaped distribution. It says that almost all the data lie within three standard deviations of the mean:
- About 68 percent of the data lie within 1 standard deviation of the mean.
- About 95 percent lie within 2 standard deviations.
- About 99.7 percent lie within 3 standard deviations.
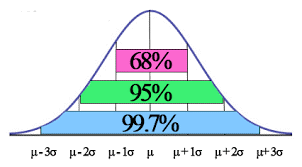
In the notation, mu is the mean and sigma is the standard deviation. The exact values for a normal curve are in this table.
| Range | Exact share of data | Rounded in the rule |
|---|---|---|
| mu plus or minus 1 sigma | 68.27 percent | 68 percent |
| mu plus or minus 2 sigma | 95.45 percent | 95 percent |
| mu plus or minus 3 sigma | 99.73 percent | 99.7 percent |
In probability notation: the chance that x lies between mu minus sigma and mu plus sigma is 68.27 percent. Between mu minus 2 sigma and mu plus 2 sigma it is 95.45 percent. Between mu minus 3 sigma and mu plus 3 sigma it is 99.73 percent. The live page prints 68.27 percent for the middle line, which is a copy mistake, and it gives approximately 7 percent for three sigma. Both are wrong.
Remember that exactly 95 percent of a normal curve lies within 1.96 standard deviations. Two standard deviations is a handy round number, and the rule uses it.
Why It is Called Empirical
Empirical means based on observation. People noticed that real measurements, such as heights and test errors, followed this pattern before it was proved for the normal curve.
Why do We Use the Empirical Rule in Statistics?
- Quick estimates. You get a rough picture of the spread without a table.
- Spotting outliers. A value more than 3 standard deviations from the mean happens in only about 0.27 percent of cases.
- Quality control. Three sigma limits are the basis of control charts.
- Sanity checks. If your data do not follow the rule, the data may not be normal.
The live page says that the rule helps with forecasting when real data are hard to obtain. The rule does not predict future values. It describes how data spread around the mean, so it helps you estimate what a whole population looks like from its mean and standard deviation.
Limit: the rule is for normal, or roughly bell shaped, data. It does not apply to skewed data, as shown below.
How to Use the Empirical Rule?
- Check that the data are roughly bell shaped. A histogram is enough.
- Find the mean (mu) and the standard deviation (sigma).
- Calculate the three ranges: mu plus or minus sigma, mu plus or minus 2 sigma and mu plus or minus 3 sigma.
- Attach the shares: about 68, 95 and 99.7 percent of the data lie in those ranges.
- Answer the question, such as how common a value is, or what share is outside a range.
Tip for tails: the remaining share is split in two equal tails, because the curve is symmetric. Outside two sigma, there is 4.55 percent, or about 2.5 percent on each side. Outside three sigma, there is 0.27 percent, or about 0.135 percent on each side.
Empirical Rule Example
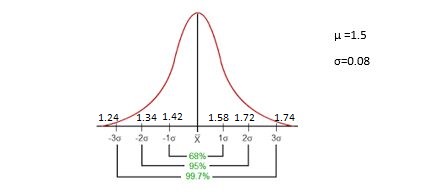
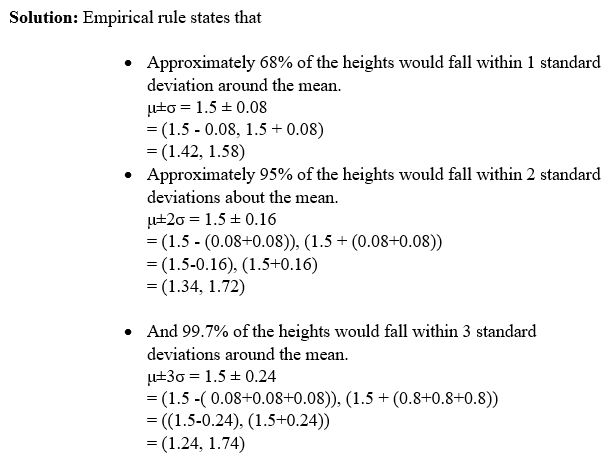
The live page: the heights of Class 6 students follow a normal distribution. The mean is 1.5 and the standard deviation is 0.08. Classify the data with the empirical rule. The page gives no units. I assume metres.
| Range | Calculation | From to | Share of students |
|---|---|---|---|
| 1 sigma | 1.5 plus or minus 0.08 | 1.42 to 1.58 | About 68 percent |
| 2 sigma | 1.5 plus or minus 0.16 | 1.34 to 1.66 | About 95 percent |
| 3 sigma | 1.5 plus or minus 0.24 | 1.26 to 1.74 | About 99.7 percent |
Reading the table:
- About 68 percent of students are between 1.42 and 1.58 metres tall.
- About 95 percent are between 1.34 and 1.66 metres.
- Almost all, 99.7 percent, are between 1.26 and 1.74 metres.
Is a 1.66 Metre Student Unusual?
1.66 is exactly 2 sigma above the mean. From the rule, about 5 percent are outside the 2 sigma range, and half of them are on the tall side, so about 2.5 percent of students are taller. The exact figure is 2.275 percent. So the rule is close, and the student is tall, but not extremely rare. In a class of 40, you would expect about one student that tall.
My simulation with 100,000 made up students agreed with the rule: 68.23, 95.46 and 99.73 percent fell within 1, 2 and 3 standard deviations.
The Link with Z Scores
A z score tells you how many standard deviations a value is from the mean: z = (x minus mu) divided by sigma. The empirical rule is a shortcut for z scores of 1, 2 and 3. For the 1.66 metre student, z = (1.66 minus 1.5) divided by 0.08 = 2.
What If the Data are Not Normal?
The rule is only a rule of thumb for bell shaped data. For skewed data, the shares are different. I simulated 100,000 waiting times, which are strongly skewed with a mean near 10, and measured the shares within 1, 2 and 3 standard deviations.
| Range | Skewed data | Normal curve |
|---|---|---|
| 1 sigma | 85.99 percent | 68.27 percent |
| 2 sigma | 95.03 percent | 95.45 percent |
| 3 sigma | 98.18 percent | 99.73 percent |
The shares are quite different at 1 sigma and at 3 sigma. The 2 sigma figure happens to be close, but that is a coincidence, so do not rely on it. For data that are not bell shaped, use a method that does not assume the shape.
Chebyshev’s Inequality: A Safe Alternative
Chebyshev’s inequality works for any distribution with a finite variance. It says that at least 1 minus 1 divided by k squared of the data lie within k standard deviations. For k = 2, that is at least 75 percent. For k = 3, that is at least 88.9 percent. These are much weaker than 95 and 99.7 percent, but they are guaranteed.
| Range | Empirical rule (normal data) | Chebyshev (any data) |
|---|---|---|
| 2 sigma | About 95 percent | At least 75 percent |
| 3 sigma | About 99.7 percent | At least 88.9 percent |
Check the Empirical Rule in Python
I ran the code below, and the output is real.
Common Mistakes to Avoid
| Mistake | Fix |
|---|---|
| Writing 68 percent for two sigma | Two sigma is about 95 percent |
| Writing 7 percent for three sigma | Three sigma is about 99.7 percent |
| Using the rule on skewed data | It is for bell shaped data |
| Saying the rule forecasts the future | It describes the spread around the mean |
| Forgetting that the tails are split evenly | Half of the outside share is on each side |
| Mixing up the standard deviation with the variance | Sigma is the square root of the variance |
| Leaving out units in the example | State metres, kilograms and so on |
| Spelling it emperical | The right spelling is empirical |
Practice Questions
- Test scores are bell shaped with a mean of 70 and a standard deviation of 5. Between what scores do about 95 percent of the students fall?
- For the same scores, what share scored above 80?
- What share of a normal distribution lies between mu minus sigma and mu plus 2 sigma?
- A data set is strongly skewed. Can you use the empirical rule?
Answers: 1) 60 to 80, since 70 plus or minus 10. 2) 80 is 2 sigma above the mean. About 2.5 percent, with 2.275 percent exactly. 3) 34 percent plus 47.5 percent, 81.5 percent, since half of 68 is 34 and half of 95 is 47.5 (exactly 81.86). 4) No. Use Chebyshev’s inequality or a method that does not assume the shape. These are my own answers, so please recheck them before publishing.
The empirical rule is a pocket tool: 68, 95 and 99.7. Check that the data are bell shaped first, find the mean and the standard deviation, and you can judge in seconds what is usual and what is rare.
